Why No RPi
For a few years I used a Raspberry Pi 4 (RPi) as a Pi-hole and Wireguard server on my home network. An RPi 4 is overpowered for that sort of thing, but I had it, so I figured I might as well use it.
Over the last few weeks I noticed increasing problems with it. The best I can tell is that the RPi Micro SD card reading/writing hardware was somehow broken. The Micro SD card I had in it originally proved bad when I tried imaging it with a fresh OS install. A different card could successfully be imaged, but when I booted the RPi from it, some programs wouldn't run because they were corrupt.
I thought about buying a replacement RPi, but because of the RAMpocalypse, prices have gone through the roof. An equivalent new RPi 4 would cost $55, when I'm sure I purchased the original one for much less than that. With shipping it was looking like a $70-80 purchase, which seemed ridiculous.
In the end, I decided to simply run the Pi-hole and Wireguard services as Docker containers on the Mac Mini M4 I use as a media center. I leave the Mac Mini running all the time anyway, it uses only 4 Watts at idle, and it's more than capable of running these services.
Looking at pricing of new RPis, including the newest RPi 5, it got me thinking about the value proposition of the RPi 5 at the moment. The RPi was developed to be a low-cost, versatile single-board computer with many applications. All RPis can be used for various general and specialty computing projects, see the wide variety of RPi HATs available. However, with the newest RPi 5, they are trying to make the argument that it's becoming a general purpose computer for everyday use. They even highlight that the RPi 5 can drive dual 4K monitors at 60 Hz, not something I would associate with cheap computing.

Let's look at this complete RPi 5 kit. It comes with all you need to get up and running, minus a monitor, keyboard, and mouse. A 256GB SSD kit with 8GB of RAM costs $320. The kit includes active cooling, which is required to achieve maximum performance. A base RPi 5 with 8Gb of RAM costs $175, which means the rest of the kit costs $145.
Let's compare this to a base Mac Mini M6. This comes with 256 GB of SSD storage and 16GB of RAM for $899. Like the RPi kit, it comes with everything you need save a monitor, keyboard, and mouse.
Using a $305 RPi 5 with 16GB of RAM to match the Mini (making the RPi kit $305 + $145 = $450), below I compare the speeds of these computers. I'm using this Mac Mini M6 benchmark and this RPi 5 benchmark.
| Product | Single Core | Multicore | Price |
|---|---|---|---|
| RPi 5 | 878 | 2,089 | $450 |
| Mini M6 | 4,661 | 20,525 | $899 |
| M6/RPi 5 | 5.3 | 9.8 | 2 |
We can see that the Mac Mini is over 5x faster in single core, and almost 10x faster in multicore, while the Mini costs only 2x more. That is a devastating price to performance ratio for the RPi. But wait!, you say, you can still buy two RPis for one Mini, which if you're on a limited budget (say, in a school), it really helps. But wait!, I respond, you still need to buy monitors, keyboards, and mice, which cost the same regardless if they're connected to a Mini or a RPi. The price savings with RPis isn't as big as you might think.
The true value proposition of an RPis are the GPIO pins which enables tons of fun and interesting computing projects. My solar water heater uses a RPi 3B+ and its GPIO pins to collect data and act as the thermostat. The tough spot that the RAMpocalypse has put RPi 5s is that this value proposition has been overtaken by component pricing, making the RPi 5 a poor choice for a general purpose computer. There might be situations where a faster RPi is needed when using the GPIO pins, but that's getting potentially niche. I would guess that most things you would need an RPi for could be done with one of the older and less expensive models.
Perhaps once the RAMpocalypse has passed the RPi 5 will again become an economical choice for hobby computing, but sadly, it isn't right now.
Useful Command Line Utilities
Recently I've been doing a little tuning of my shell environment, swapping old tools for new ones and tweaking various settings. I thought I'd highlight a few of them.
Ghostty
For years I used iTerm2 as a replacement for the default Mac OS Terminal app. Recently I've switched to Ghostty. It's just as configurable in the ways I care about as iTerm2, but much, much faster. I sometimes have reason to paste a decent amount of text into the terminal and Ghostty handles it much faster than iTerm2. Overall it just feels more modern and slicker than iTerm2.
Starship

In the screenshot above you can see a few shell prompts showing what Starship can do. For example, when you're in a folder containing a programming project, it will show you the language in use. For example in the "sshaws_rust" folder you can see "🦀 v1.97.1", which shows my current version of Rust installed. Similarly you can see "☕️ v17.0.8" for Java, "🆂 v3.8.4" for Scala, and "🐍 v3.12.12" for Python. It also shows you stats about your machine (e.g. free RAM), what directory you're currently in, or how long a command took to run.
In the screenshot below, you can see the "🌏 marzipan" which shows that this is a remote machine named "marzipan," which helps prevent confusion about what machine you're on.

zoxide
I haven't been using this very long, and I'm still getting used to it, but
zoxide is a handy way to navigate
around your folder hierarchy.
In the first screenshot above you can see that z core took me straight to that
directory and zi opens an interactive search function.
fzf
Like most, I'm sure, I end up typing the same or very similar commands repeatedly. "Ctrl-r" is the standard way of searching for previous commands. fzf turbo-charges this and works very well.
bat

The Unix/Linux command cat is
over fifty years old, and I've been using it for almost thirty.
bat replaces it and includes syntax
highlighting and line numbers.
Because I've been using cat for so long, and have muscle memory for cat,
I've set an
alias
from cat to bat.
eza

Combined with a Nerd Font
(I use "Inconsolata Nerd Font Mono"),
eza replaces the built in
ls and ls -l with a much fancier directory listing.
In the screenshot above you can see that each document type gets a little
icon, and there are far more color codes than plain ls.
The columns shown in the -l view can also be customized much more than
vanilla ls.
ripgrep

Many years ago I started using grin
which is (was?) a recursive grep utility.
Being a Python 2 utility
and Python 2 reached end-of-life in 2020,
I switched to grin3.
Now I'm getting used to using
ripgrep, which A) is faster than
grin3, and B) is maintained while grin3 is not.
oh my zsh
I've been using zsh for years, and oh my zsh helps configure it with all kinds of goodies.
Raycast

It's not a command line utilty, but Raycast has proven invaluable. It's a supercharged Spotlight replacement. It has many useful features, not least of which is the Clipboard History. The Calculator is great for quick math and unit conversion.
Confguration Files
If you want to see my configuration files, just drop me a line!
ETL Pipeline Improvements
One of my primary responsibilities at my current job is ownership of the ETL pipeline that brings in the data upon which we run our business. Every day it processes hundreds of gigabytes of data, cleaning and normalizing it, and outputting it in several different forms.
For a few years I have been using a Hadoop-based mrjob pipeline on top of AWS EMR. It replaced a (I kid you not) Redshift-based pipeline that was hugely expensive (that I didn't write). It's been very reliable. For the last year or two the only failures have been when AWS's systems have had issues, something I can't do anything about. Despite this reliability, it hasn't been perfect. The biggest problem with it is that it's expensive to run. There are few reasons why it's been so expensive:
-
EMR adds a 25% upcharge on all resources used. It is reasonable for AWS to charge something because EMR is a useful service with added value. However, in my opinion, 25% is too high for what it does. AWS already gets paid plenty because you're using their other services underneath it (mainly EC2 virtual computers and EBS block storage), so the extra mark-up feels like a big cash-grab. It is, of course, entirely possible to run Hadoop on AWS without using EMR. But it is a hassle, and it's likely that AWS has figured out that 25% is the inflection point between too expensive and not worth the hassle
-
Hadoop isn't the most efficient way of doing things. Newer tools, notably Spark, have surpassed Hadoop in both speed and features. I originally used Hadoop because I wasn't happy with how Spark needed quite a bit more memory than Hadoop for a similar operation, but over time I became less and less satisfied with my inability to speed up certain parts of the process
-
AWS offers spot compute instances, which are virtual computers that are significantly cheaper than on-demand instances. The difference is that on-demand nodes are yours as long as you want them, while spot instances can be taken away at any time with only two minutes warning.
One of Hadoop's killer features is that during a MapReduce cycle, if one or more worker nodes goes away (for whatever reason including spot node removal), in most cases it can recover and redo any lost results.
However, the EMR pipeline used a multi-step MapReduce process. Unfortunately, Hadoop cannot recover lost results from earlier, fully completed MapReduce cycles. This means that in order to run the pipeline, it had to have enough on-demand instances that the data that needed to be preserved across cycles fit on them. This raised the cost considerably when compared to an all-spot pipeline run
Earlier this year I decided it was time to start looking at how to rewrite the pipeline to dramatically lower costs. I saw two possible ways forward:
-
Choose a modern, high performance tool like Spark/PySpark or Dask that would still run on EMR but hopefully would be much faster
-
Abandon EMR entirely (and its 25% surcharge) and write something that could run completely on spot instances and use S3 for storage, which is four to five times cheaper than EBS
After some thought, I decided that the second option was the better choice. If I could figure it out, it offered the best possible outcome. The pipeline runs once per day, meaning that it has 24 hours to finish before the next run needs to start. Ultimately, high performance was less important than lowering costs.
I have been using Polars quite a bit and have been (mostly1) impressed with its speed and functionality. It is written in Rust, which is one of the fastest programming languages. Polars has a Python-facing API as a first-class member of the project. Rust has an ever-growing library of packages that I've found are high-quality and well documented (in contrast to my experience with cough R packages). The crucial difference between Polars and Hadoop/Spark/Dask is that Polars runs on only one node at a time (it can and does use all the CPU cores), while all of the others can run on multiple nodes. If I could figure out how to slice up the pipeline into chunks that would work on separate instances, I believed I could use Polars in place of Hadoop.
Jumping to the end of the story, I was able to convert the pipeline to use Polars, and to great success. I use a simple pattern for each step. An orchestration process builds a list of work which is submitted to SQS. An EC2 spot fleet is created which launches workers that consume the work. The input and output of the work is stored on S3. The workers send success or failure messages to a callback queue on SQS, which is monitored by the orchestration process. If a spot node goes away interrupting work, the work will be picked up by a different node once the message returns to availability. Once the work is done for a step (i.e. all work has generated a callback), the orchestration process kills the spot fleet and continues to the next step (or sends an error message for a human to figure out).
The bottom line is that the cost has dropped by roughly 85%, primarily due to the following reasons:
-
Polars has the concept of LazyFrames which are data objects that are not realized in memory nor computation until Polars is told to do so. Operations and filtering can be applied to them and Polars can do the work in parallel with efficiency tricks that overall increases speed without loading the whole dataset into memory at once. The combination of sink_parquet with PartitionByKey is effectively a MapReduce operation that is much faster than Hadoop on similar hardware
-
AWS has "regions" and "availability zones (AZs)" which are the physical locations where cloud compute happens. Each AZ is a distinct data center (or close by data centers) within a region. When running an EMR job, you are restricted to a single AZ largely because AWS charges for cross-AZ data transfer, and EMR jobs are very loquacious across the network. There's also increased network latency between AZs. Running and EMR job in multiple AZs would hugely impact performance and cost.
Because the new pipeline reads from and saves data to S3, and there are no cross-AZ charges for accessing S3 within a region, it doesn't matter which AZ the workers run in. This means that the spot fleets can target all AZs within the region, unlike EMR
-
When launching an EC2 fleet, you must specify one or more launch templates, which describe how to launch each instance in terms of OS and installed software. AWS EC2 offers instances using x86 processors from Intel and AMD, and ARM instances using AWS Graviton processors. Conveniently, the pipeline doesn't require any processor-specific features. Therefore, I created two AMIs, one for each of x86 and ARM, which allows the spot fleet to target any and all of Intel, AMD, and Graviton instances
-
The pipeline requirements for each step basically comes down to number of CPU cores and amount of RAM, more or less of each depending on what the step is doing. The upshot of all of the above is that for a given step all the pipeline cares about is the resources of the node, not what kind of node it is. Of course, not all instances are the same speed, but the cost of an instance is roughly proportional with its speed, so it all works out. This means that for a given step, across all AZs and EC2 instance types, there can be over 100 distinct resource combinations to pick from. This basically guarantees spot availability at all times
-
The pipeline uses a fair number of User Defined Functions. Polars supports UDFs written in Python, Numba, and Rust using PyO3. By using the latter two, basically all of the inner loops and heavy computation in the pipeline happens in compiled C or Rust. This, in my opinion, is a really nice way of doing things. Let Python handle moving data around and high-level stuff, and run all the heavy computation in compiled code.
Overall, I'm very pleased about the results of this work. The goal was to save money, and it has done that. I wasn't expecting 85% savings (I'm not sure what I was hoping for), but I feel quite good about that.
A Polars Memory Leak Trick
I am a big proponent of Polars for data analysis. It combines the ease of Python with the speed of Rust. In many cases it allows working with very large datasets very convenient. I have even written about it before on this blog.
Despite the nice things I wrote above about Polars above, it is still a work in progress. One big issue it has is less than ideal memory management when working with very large dataframes as discussed in this ticket on github. I have seen similar issues with Polars, where for no explicable reason it will run my machine out of memory. Below is a simplified example of a situation that I have run into this problem.
This example is in the middle of a processing pipeline. I have created a set of
Parquet files in which
I am including an ff column because I want to be able to filter on it.
The entire set of Parquet files in dirname would not fit in memory, but
a subset will, and I can process these subsets separately and
combine the reduced dataframes at the end to achieve the same result.
The distribution of values in ff is very even,
meaning that each subset uses very closely the same amount of memory.
Because ff is in the Parquet files, Polars can use
predicate pushdown
to filter on ff at the read step, meaning that the full dataset is never
read into memory.
Indeed, the first few loops of this process work quite well. The filtered subsets fit into memory, and reduced dataframes are calculated. However, eventually Polars stops managing memory correctly and things go bad, and the machine runs out of memory.
import polars as pl

data = pl.scan_parquet(dirname)

reduced = []

# this will eventually run out of memory
for ff in range(N):
    print("doing", ff)
    # note that data is untouched each cycle
    data1 = data.filter(pl.col("ff") == ff)
    # Do some various LazyFrame manipulations on data1; we don't call
    # .collect() until below
    reduced.append(data1.collect())

reduced_data = pl.concat(reduced)
If the situation is amenable, there is a way around this.
By running the Polars steps in a subprocess using
multiprocessing,
we can force Polars to free memory after each cycle by shutting down
the process that runs Polars every cycle.
Of course, there is a little bit of additional overhead here.
Starting the subprocess takes a little time, as does re-scanning the
directory of files in scan_parquet().
There is also some cost in
un/pickling
the reduced dataframe between the main process and the Polars subprocess.
But if the data is large enough to resort to chunking like this, these extra costs
are rounding errors, and are not worth worrying about.
from multiprocessing import Process, Queue, set_start_method

def worker(dirname, ff, out_q):
    data = pl.scan_parquet(dirname)
    data = data.filter(pl.col("ff") == ff)
    # Do some various LazyFrame manipulations on data; we don't call
    # .collect() until below
    out_q.put(data.collect())

if __name__ == "__main__":
    set_start_method("spawn")

    out_q = Queue()

    # this works to completion
    for ff in range(N):
        print("doing", ff)
        p = Process(target=worker, args=(dirname, ff, out_q), daemon=True)
        p.start()
        reduced.append(out_q.get())
        p.join()

    reduced_data = pl.concat(reduced)
I think this trick very simply illustrates the way that Polars is currently mismanaging memory. The two examples above are doing the same basic thing, but one works and the other doesn't. In fact, if I run the two methods above and watch memory use in real time, the two methods have similar behavior for some number of cycles. The memory use goes up and down as the filtered data is processed and cleaned up each cycle. This indicates that Polars can do memory management correctly, but for some reason after too many cycles, Polars stops freeing memory. In the github ticket linked above, it's suggested that a fix might have a performance cost. Hopefully something can be done about this that both prevents the memory leak and doesn't cost too much in performance. For now, this trick can be useful in the right situations.
Go Big To Go Home
The first step of data science when working with new a dataset is to understand the high-level facts and relationships within the data. This is often done by exploring the data interactively by using something like Python, R, or Matlab.
Recently I've been exploring a new dataset. It's a pretty big dataset: a few hundred gigabytes of data in compressed Parquet format. A rule of thumb is that reading data off disk into memory takes ten or twenty times the memory than the storage the data uses on disk. For this dataset, that could equal more than ten terabytes of memory, which in 2025 is still a pretty ridiculous amount of memory on a single machine. It is for this reason that working with data this size requires tools that allow you to work with the data without loading all of it into memory at once.
One of these tools is Polars. Quoting the Polars home page: "Want to process large data sets that are bigger than your memory? Our streaming API allows you to process your results efficiently, eliminating the need to keep all data in memory." It's still a bit rough around the edges with some unfinished and missing features, but overall it's a powerful and capable tool for data analysis. Lately I've been using Polars more and more, taking advantage of this "streaming" ability.
On the other hand, sometimes it's easiest to do things directly and skip all the low-memory "streaming" tricks. If I can get an answer more quickly by simply using lots of memory, especially if it's something I'm doing only once and not putting into a repeated process, then this can be the right choice. Polars can do "streaming" analysis, but at a certain point it has to coalesce things into an answer, and sometimes that answer can use a significant amount of memory.
There are many negative aspects of cloud computing that I won't get into here. However, there are some good things, and one of them is that you can scale up and down resources as needed. All cloud providers, like Amazon Web Services and Google Cloud Platform offer many services and in particular Virtual Machines. When running a virtual machine you can choose the hardware specifications in terms of CPU kind and core count, amount of RAM, and other features like network speeds, GPUs, or SSDs. A virtual machine can be booted on one hardware configuration, shut down, and the rebooted on a different configuration as needed. It's as if you took the hard drive out of your laptop and put it in a big workstation. All your data and settings are still there, but you've upgraded the hardware. This is something I take advantage of frequently!
I was attempting to do a certain analysis of the new dataset on an EC2 virtual machine and I kept running out of memory. Instead of switching to some low-memory tricks, I decided to see if I could save some time by simply rebooting my virtual machine on one of the larger instances AWS offers: a r7i.48xlarge. This has 192 CPU cores and 1,536 GB of RAM. It costs $12.70 per hour. I get paid more than $12.70 per hour, so if booting up a huge machine like this saves me even a little time, it's worth it.
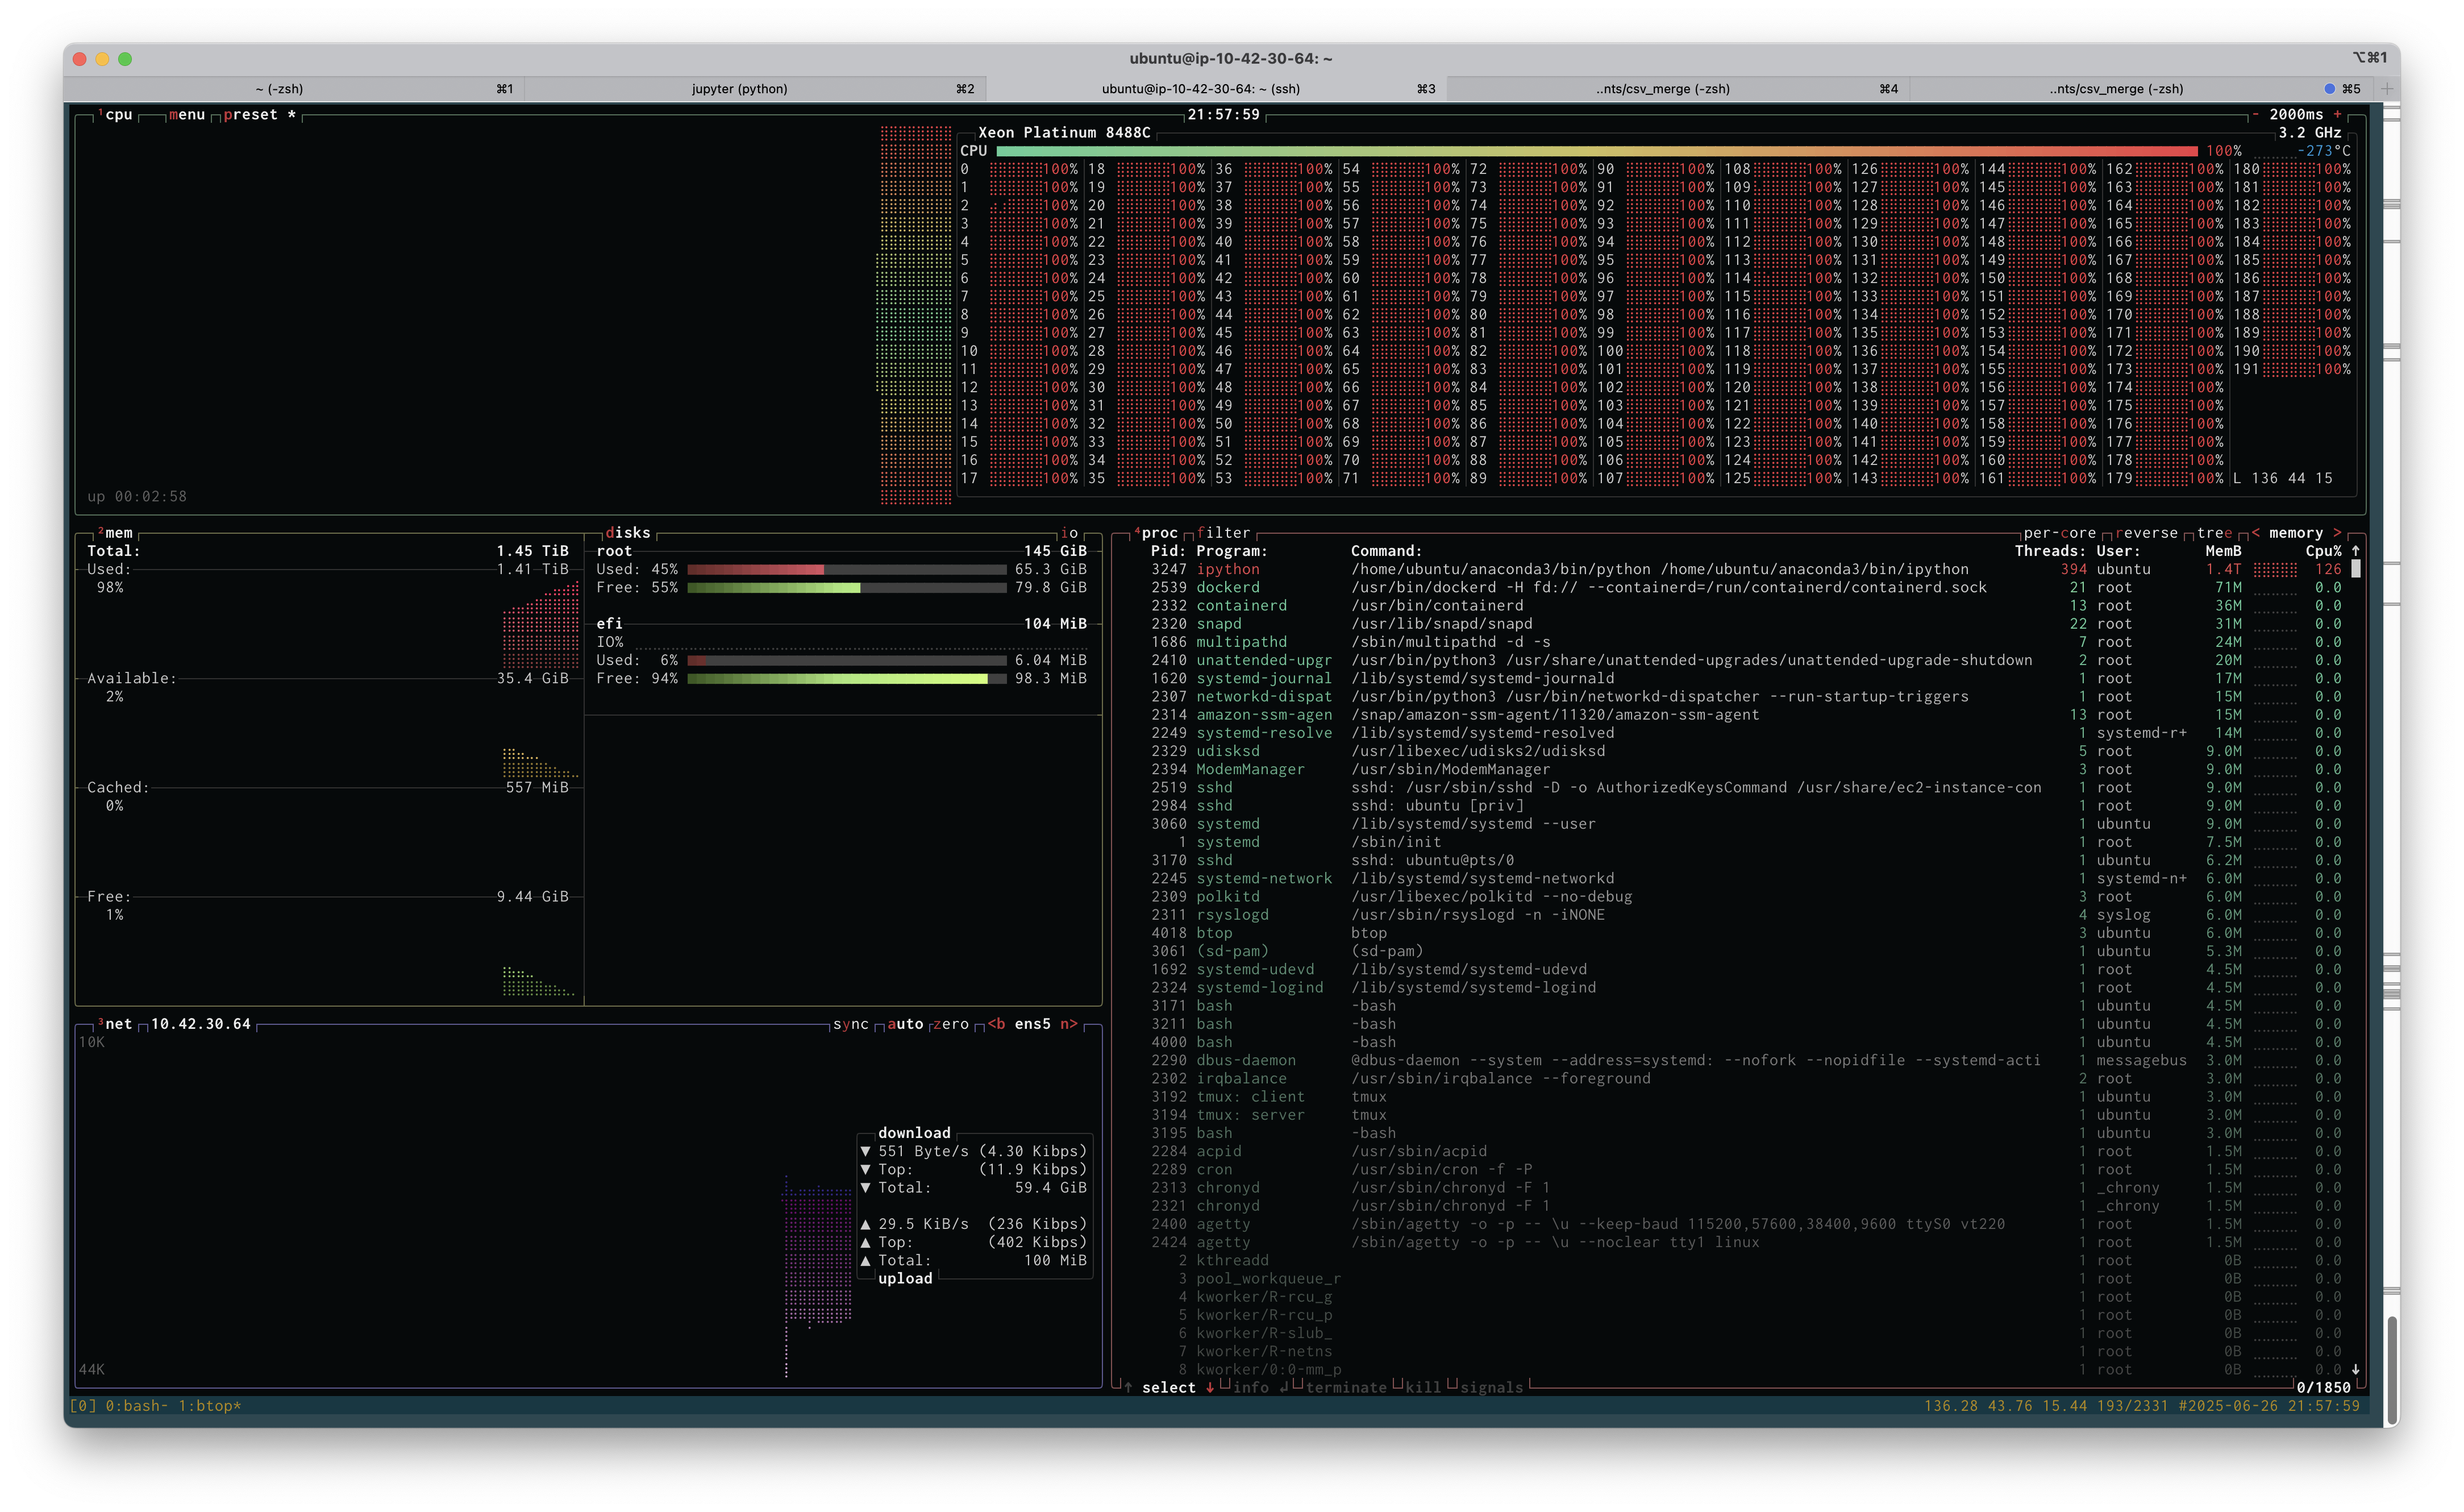
Above is a screenshot of btop running on the r7i.48xlarge instance while I attempted to run my analysis. If you click on the image, you'll see the full size screenshot. You'll see that I'm about to run out of memory: 1.41TB used of 1.45TB. You'll also see that I'm using all 192 cores at 100% load (the cores are labeled 0-191). Unfortunately, throwing all this memory at the problem didn't work, I ran out of memory, and I had to resort to being more clever. Being clever took more time, of course, but if the high-RAM instance had worked, it would have paid off.
Playing with various server configuration tools (like this one) shows that the r7i.48xlarge would cost at least $60,000. This is not something that I need very often, and purchasing something this large would be ridiculous. However, renting it for half an hour, if it saves me a few hours, is definitely worth it. Also, it's kind of fun to say "yeah, I used 1.5TB of memory and 192 cores and it wasn't enough."
Polars scan_csv and sink_parquet
The documentation for polars is not the best,
and figuring out how to do this below took me over an hour.
Here's how to read in a headerless csv file into a
LazyFrame using
scan_csv
and write it to a parquet file using
sink_parquet.
The key is to use with_column_names and
schema_overrides.
Despite what the documentation says, using schema doesn't work as you
might imagine and sink_parquet returns with a cryptic error about
the dataframe missing column a.
This is just a simplified version of what I actually am trying to do, but that's the best way to drill down to the issue. Maybe the search engines will find this and save someone else an hour of frustration.
import numpy as np
import polars as pl

df = pl.DataFrame(
    {"a": [str(i) for i in np.arange(10)], "b": np.random.random(10)},
)
df.write_csv("/tmp/stuff.csv", include_header=False)

lf = pl.scan_csv(
    "/tmp/stuff.csv",
    has_header=False,
    schema_overrides={
        "a": pl.String,
        "b": pl.Float64,
    },
    with_column_names=lambda _: ["a", "b"],
)

lf.sink_parquet("/tmp/stuff.parquet")
Infinite Mac
Sometime in 1994 me and my father went to a small computer show in the UC Berkeley Student Union building (which appears to now be named The MLK Jr. Building). It was probably a Macintosh oriented event, and among the various tables there was a Power Macintosh 6100 on display. The first Macintosh computers used Motorola 68000 series chips, and in 1994 Apple was making a transition to PowerPC chips. The 6100 was the first Mac to use a PowerPC chip, and seeing one in person was exciting. PowerPC chips promised a leap in performance, and I wanted one very badly. I had to wait at least a year to enter the PowerPC world when my father bought a PowerMac 8500.
Some time ago a Mac enthusiast released a website, Infinte Mac, that allows you to run old Mac operating systems in your browser. It starts with System 1.0, and has many releases all the way up to MacOS 9, the last version of the original Macintosh OS before they made the switch to the Unix-based OS that's still in use today. I suggest you try it out, it's really fun! I like playing with the various options because it reminds me of using and playing with computers from my childhood. The machines include quite a bit of pre-installed software. Many of the games I played actually work, which is impressive. It also shows how interfaces have evolved and mostly improved over the last 30-40 years.
The website uses various software emulators (including Basilisk II and SheepShaver) to simulate specific CPUs. To rephrase, what's happening is that the classic Macintosh system is running inside of a bit of software that, on the fly, translates old CPU instructions so that they run on a different CPU type. This is naturally less efficient than running instructions directly on a real CPU.
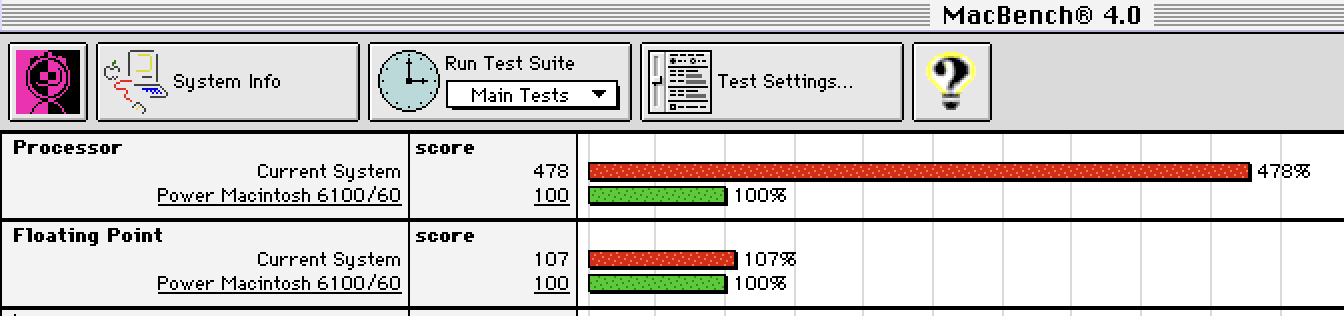
Recently I tried running a benchmark program (Macbench) in the emulator. Below is what I got on my M1 Max MacBook Pro. As you can see, the processor score is nearly five times faster than the PowerMac 6100 I wanted so long ago. Considering that my laptop has ten cores, my laptop is roughly 50 times faster than the PowerMac 6100 while running in emulated mode. It's been 30 years and of course progress progresses, but I still find it super impressive how much faster my laptop is using software emulation. Sitting here on my lap is a machine that's orders of magnitude better than what my 14 year old self wanted so badly. Huzzah!
Earlier this month I bought a Mac Mini M4 to replace our six year old Mac Mini i3. As you can see, the M4 is over seven times faster than the PowerMac 6100. Being three generations newer than my laptop, it naturally gets a better score.
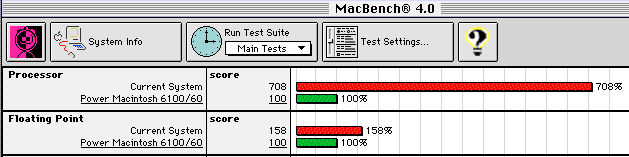
As an aside, I think that the floating point functions must be emulated in a less efficient way than the main processor functions. I don't think that the relatively low floating point scores are representative of the actual M1/M4 CPU performance.
How I Got a 327x Speedup Of Some Python Code
I don't usually post code stuff on this blog, but I had some fun working on this and I wanted to share!
My colleague, Abhi, is processing data from an instrument collecting actual data from the real world (you should know that this is something I have never done!) and is having some problems with how long his analysis is taking. In particular, it is taking him longer than a day to analyze a day's worth of data, which is clearly an unacceptable rate of progress. One step in his analysis is to take the data from all ~30,000 frequency channels of the instrument, and calculate an average across a moving window 1,000 entries long. For example, if I had the list:
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
and I wanted to find the average over a window of length three, I'd get:
[1, 2, 3, 4, 5, 6, 7, 8]
Notice that I started by averaging [0, 1, 2]=>1, as this is the first way to come up with a window of three values. Similarly, the last entry is [7, 8, 9]=>8. Here is a simplified version of how Ahbi was doing it (all of the code snippets shown here are also available [here][1]):
def avg0(arr, l):
    # arr - the list of values
    # l - the length of the window to average over
    new = []
    for i in range(arr.size - l + 1):
        s = 0
        for j in range(i, l + i):
            s += j
        new.append(s / l)
    return new
This function is correct, but when we time this simple function (using an IPython Magic) we get:
# a is [0, 1, 2, ..., 29997, 29998, 29999]
a = np.arange(30000)
%timeit avg0(a, 1000)
1 loops, best of 3: 3.19 s per loop
Which isn't so horrible in the absolute sense -- 3 seconds isn't that long compared to how much time we all waste per day. However, I neglected to mention above that Abhi must do this averaging for nearly 9,000 chunks of data per collecting day. This means that this averaging step alone takes about 8 hours of processing time per day of collected data. This is clearly taking too long!
The next thing I tried is to take advantage of Numpy, which is a Python package that enables much faster numerical analysis than with vanilla Python. In this function I'm essentially doing the same thing as above, but using Numpy methods, including pre-allocating space, summing values using the accelerated Numpy .sum() function, and using the xrange() iterator, which is somewhat faster than plain range():
def avg1(arr, l):
    new = np.empty(arr.size - l + 1, dtype=arr.dtype)
    for i in xrange(arr.size - l + 1):
        new[i] = arr[i:l+i].sum() / l
    return new
This provides a healthy speed up of about a factor of eight:
%timeit avg1(a, 1000)
1 loops, best of 3: 405 ms per loop
But this still isn't fast enough; we've gone from 8 hours to just under an hour. We'd like to run this analysis in at most a few minutes. Below is an improved method that takes advantage of a queue, which is a programming construct that allows you to efficiently keep track of values you've seen before.
def avg2(arr, l):
    new = np.empty(arr.size - l + 1, dtype=arr.dtype)
    d = deque()
    s = 0
    i = 0
    for value in arr:
        d.append(value)
        s += value
        if len(d) == l:
            new[i] = s / l
            i += 1
        elif len(d) > l:
            s -= d.popleft()
            new[i] = s / l
            i += 1
    return new
And here we can see that we've cut our time down by another factor of 4:
%timeit avg2(a, 1000)
10 loops, best of 3: 114 ms per loop
This means that from 8 hours we're now down to roughly 13 minutes. Getting better, but still not great. What else can we try? I've been looking for an excuse to try out Numba, which is a tool that is supposed to help speed up numerical analysis in Python, so I decided to give it a shot. What makes Numba attractive is that with a single additional line, Numba can take a function and dramatically speed it up by seamlessly converting it into C and compiling it when needed. So let's try this on the first averaging function:
@jit(argtypes=[int32[:], int32], restype=int32[:])
def avg0_numba(arr, l):
    new = []
    for i in range(arr.size - l + 1):
        s = 0
        for j in range(i, l + i):
            s += j
        new.append(s / l)
    return np.array(new)
In the line beginning with @jit, all I have to do is describe the input and the output types, and it handles the rest. And here's the result:
%timeit avg0_numba(a, 1000)
10 loops, best of 3: 21.6 ms per loop
What is incredible here is that not only is this roughly 5 times faster than the queue method above, it's a ridiculous 147 times faster than the original method and only one line has been added. We've now reduced 8 hours to about 4 minutes. Not bad!
Let's try this on the second averaging method, which if you recall, was substantially better than the original method:
@jit(argtypes=[int32[:], int32], restype=int32[:])
def avg1_numba(arr, l):
    new = np.empty(arr.size - l + 1, dtype=arr.dtype)
    for i in xrange(arr.size - l + 1):
        new[i] = arr[i:l+i].sum() / l
    return new
%timeit avg1_numba(a, 1000)
1 loops, best of 3: 688 ms per loop
That's interesting! For some reason I don't understand, this is actually slower than the un-optimized version of avg1. Let's see if Numba can speed up the queue method:
@jit(argtypes=[int32[:], int32], restype=int32[:])
def avg2_numba(arr, l):
    new = np.empty(arr.size - l + 1, dtype=arr.dtype)
    d = deque()
    s = 0
    i = 0
    for value in arr:
        d.append(value)
        s += value
        if len(d) == l:
            new[i] = s / l
            i += 1
        elif len(d) > l:
            s -= d.popleft()
            new[i] = s / l
            i += 1
    return new
%timeit avg2_numba(a, 1000)
10 loops, best of 3: 77.5 ms per loop
This is somewhat better than before, but still not as fast as avg0_numba, which comes in at roughly 20ms. But what if I really try hard to optimize the queue method by using only Numpy arrays?
@jit(argtypes=[int32[:], int32], restype=int32[:])
def avg2_numba2(arr, l):
    new = np.empty(arr.size - l + 1, dtype=arr.dtype)
    d = np.empty(l + 1, dtype=arr.dtype)
    s = 0
    i = 0
    left = 0
    right = 0
    full = False
    for j in xrange(arr.size):
        d[right] = arr[j]
        s += arr[j]
        right = (right + 1) % (l+1)
        if not full and right == l:
            new[i] = s / l
            i += 1
            full = True
        elif full:
            s -= d[left]
            left = (left + 1) % (l+1)
            new[i] = s / l
            i += 1
    return new
%timeit avg2_numba2(a, 1000)
100 loops, best of 3: 9.77 ms per loop
A ha! That's even faster, and our 3.19s are now down to 9.77ms, an improvement of 327 times. The original 8 hours are now reduced to less than two minutes. I hope you've enjoyed this as much as I have!
Update:
After chatting with a couple of my colleagues, this appears to be the fastest way to do this kind of operation:
from scipy.signal import fftconvolve
import numpy as np
a = np.arange(30000)
b = np.ones(1000) / 1000.
%timeit fftconvolve(a, b, 'valid')
100 loops, best of 3: 6.25 ms per loop
Supercomputers
Faithful readers will remember me posing with my favorite supercomputer about a year ago. Datastar is going to be turned off in a few months. When it was turned on three years ago, it was the 35th fastest computer in the world, it has since slipped to 473rd. Despite the fact it's no longer the fastest thing around, it works wonderfully, and as I write this, there are at least sixty people logged onto this machine. Everyone I know loves Datastar, and wishes it wasn't going to be turned off. I am starting to move my work and attention to the newer machines. They are faster, and have many more processors, which makes queue times short (which is the time it takes for a job I request to run)
A few months ago, Ranger was turned on. It is a Sun cluster in Texas with 63,000 Intel CPU cores. It is currently ranked fourth fastest in the world. Datastar has only 2528 CPUs (but those are real CPUs, while Ranger has mutli-core chips which in reality aren't as good). By raw numbers, Ranger is an order of magnitude better than Datastar, except that Ranger doesn't work very well. Many different people are seeing memory leaks using vastly different codes. These codes work well on other machines. I have yet to be able to run anything at all on Ranger. For all intents and purposes, Ranger is useless to me right now.
If you look at the top of the list of super computers, you'll see that a machine called Roadrunner is the fastest in the world. Notice that it is made up of both AMD Opteron and IBM Cell processors. The Cell processor is the one inside Playstation 3s. Having two kind of chips adds a layer of complexity, which makes the machine less useful. The Cell processor is a vector processor, which is only awesome for very specially written code. The machine is fast, except it's also highly unusable. I don't have access to it because it's a DOE machine, but a colleague has tried it and says he got under 0.1% peak theoretical speed out of it. Other people were seeing similar numbers. No one ever gets 100% from any machine, but 0.1% is terrible.
Computers two and three on the list are DOE machines, so I don't have access to them. On the near horizon is a machine called Kraken, in Tennessee. It's being upgraded right now, but when it's complete it will be very similar to, but faster than the fifth fastest computer on the list currently, called Jaguar. It is a Cray XT4 that runs AMD Opteron chips. I got to use Kraken recently while it was still an XT3, and it was awesome. Unlike Ranger, it actually works. As an XT4, it should be even faster than Ranger. It will also have a great tape backup system, unlike Ranger.
I am predicting that Kraken will be come my new favorite super computer, replacing Datastar. However, I think it's a shame that Datastar is being turned off even though it's still very useful and popular. When it's turned off to make way for machines like Ranger and Roadrunner(*), that's just stupid.
(*) The pots of money for Ranger, Datstar and Roadrunner are different, but you get the point. Supercomputers aren't getting better; in some cases, they're getting worse!
OpenMP
I'm all about graphs lately!
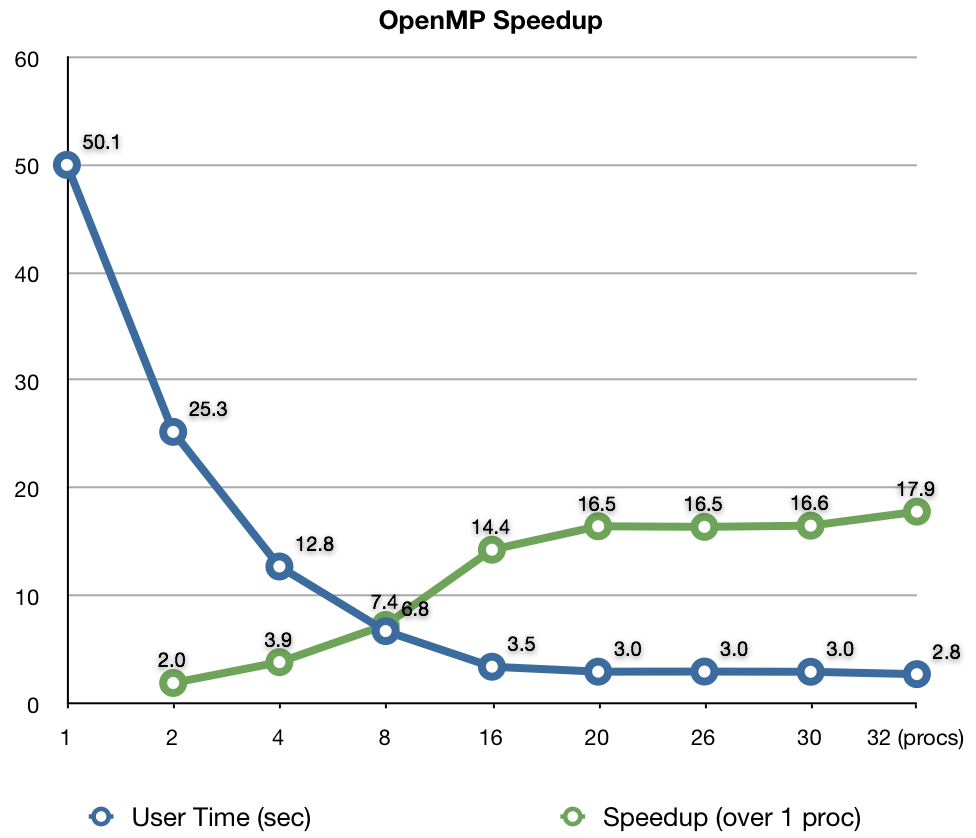
The graph above shows the speedup that a few OpenMP statements can give with very little effort. OpenMP is a simple way to parallelize a C/C++ program which allows you to run a program on many processors at once. However, unlike MPI which can run on many different machines (like a cluster), OpenMP can only be run on one computer at a time. Since most new machines have multiple processors (or cores), OpenMP is quite useful.
I've added a couple dozen OpenMP statements to the code I'm working on. The blue line shows how long (in seconds) it took me to run a test problem on between one and 32 processors. The green line shows the speedup compared to running on a single processor as a ratio of time. It is very typical of parallel programs that the speedup isn't linear and flattens out at high thread count. This small test problem deviates at 16 processors; when I do a real run (which will be much larger and the parallelization more efficient) I may see nearly linear speedups all the way to 32 processors.
I think it's pretty neat how with very little effort I was able to significantly speedup my code.