The Closest Non-Intersecting US Interstates
On our recent driving trip to Yellowstone and Montana, I had lots of time to think about random things while behind the wheel. One of them was to wonder of the major US Interstates, which two come the closest without actually intersecting? My guess was that it's some place on the East Coast, but due to my general lack of knowledge of East Coast highways, I had no idea which two it is.
Being a huge dork, I decided to figure it out.
Basically, it's actually not a very difficult thing to figure out. The steps are:
- Get the latitude and longitude coordinates for a number of points along each of the interstates.
- Determine which interstates intersect and eliminate those pairs.
- Put the coordinates for the interstates into a kD-Tree which will perform the search that determines the distance between non-intersecting highways in a fast way.
It turns out that the first step proved to be the hardest. I decided to use the data from the Open Street Map (OSM) project. This is a Google Maps-like website that is editable by anyone in the world, similar to Wikipedia. It will not give you directions like other mapping services, but it contains the geographical location of a wide variety of items, including and importantly (as the name suggests) roads. I looked into using the OSM APIs, but as far as I could tell either the APIs didn't do what I needed in an efficient way, or the servers were down. So I simply downloaded the 82 GB XML (5 GB compressed for download) dataset for the United States.
Begin rant feel free to skip to the next paragraph. I loathe XML. Any time that you have a 82 GB text file (apparently it's 200+ GB for the whole world) as your main distribution method, you're doing something wrong. Doing this project I learned as little about XML as I could to get just what I needed out of the file. Apparently the authoritative data is kept in a real database, but it appears that you can not download the data as a database. They do have a binary format description, but I can't find a link to download the data in that format. Furthermore, the world doesn't need yet another binary format. For example, they do not discuss endianness for their binary format on that wiki page, which is a big issue with binary formats. There are many other quality formats they could use (SQLite or HDF5). The binary format has a distinct Not Invented Here feel to it, which is nearly always a bad thing. Anyway, back to the main point of my rant. I don't care that the 82 GB XML file compresses down to 5 GB. Reading a 82 GB text file when you're searching for just a fraction of that data takes a long, long time, and is completely unnecessary. Every time I encounter XML it wastes my time in myriad ways. This time was no different. End rant
I'll spare you the full details and samples my low-quality Python code, but I munged the interstate data into a SQLite file, which distilled the data from 82 GB to 19 MB. Yes, that's nearly four orders of magnitude smaller. Then I used the much more convenient (and fast) SQLite file to build lists of interstate coordinates, which were fed into the kD-Tree for the nearest neighbor searches. The results are shown below. Note that there is no I-50 or I-60, and I eliminated I-45 from consideration because it's entirely within Texas, and therefore is not "major" in my opinion. I eliminated Hawaii's H-1 for the same reason. I have included links to maps showing the great circle between the nearest points of the highways. For highways that intersect, the link goes to one of the (more or less random) points of intersection.
Finally, we can see the answer I was looking for. Interstates 70 and 95 come within 5 kilometers in Baltimore at the terminus of 70, but do not intersect. So my suspicion was correct that it was somewhere in the East, so I have that to feel good about.
| X | 95 | 90 | 85 | 80 | 75 | 70 | 65 | 55 | 40 | 35 | 30 | 25 | 20 | 15 | 10 |
| 5 | 3338 | 2877 | 2826 | 690 | 2741 | 2484 | 142 | 1760 | 1822 | 910 | 1237 | ||||
| 10 | 1195 | 178 | 544 | 558 | 91 | 321 | |||||||||
| 15 | 2860 | 2423 | 2029 | 2009 | 1839 | 1272 | 1489 | 436 | 1093 | ||||||
| 20 | 804 | 764 | 615 | 173 | 283 | ||||||||||
| 25 | 2185 | 1730 | 1653 | 1453 | 1239 | 629 | 749 | ||||||||
| 30 | 1062 | 865 | 610 | 758 | 643 | 458 | 486 | 191 | |||||||
| 35 | 1404 | 985 | 569 | 516 | 358 | ||||||||||
| 40 | 587 | 550 | 347 | ||||||||||||
| 55 | 806 | 340 | 319 | 37 | |||||||||||
| 65 | 465 | 101 | |||||||||||||
| 70 | 5 | 152 | 234 | 105 | |||||||||||
| 75 | 12 | ||||||||||||||
| 80 | 413 | ||||||||||||||
| 85 | 582 | ||||||||||||||
| 90 |
p.s. If you really, really want to see the code I used for this, I can share it, but I'll have to pull out the hamsters that have taken residence in it. They're attracted to dusty littered places, you know.
Blob Identification
I have access to some of the fastest computers in the world. I can summon thousands of processors, petabytes of disk storage, and terabytes of memory with a few keystrokes. You'd think with that kind of power, analysis could be automated and done in massive pipelines. But that's not always true. Sometimes things are so subtle that the most efficient method is still to use the human eye.
Today I was pretty ill, with a sore throat and congestion. It was the kind of day for lying on the couch and watching movies. Luckily, I was able to accomplish some work that didn't require too much concentration. First, some context.
One of my current projects is looking at the centers of simulated galaxy clusters, and it is actually surprisingly difficult to find the centers of the clusters. Clusters are complicated places, with clumps of matter falling in, sloshing stuff around, making the core not exactly clear. In order to semi-automate the process, I wrote a script that makes pictures of the clusters (which have been previously identified in a automated fashion), that have density contours superimposed. The density contours are analogous to the lines on a topographical map.
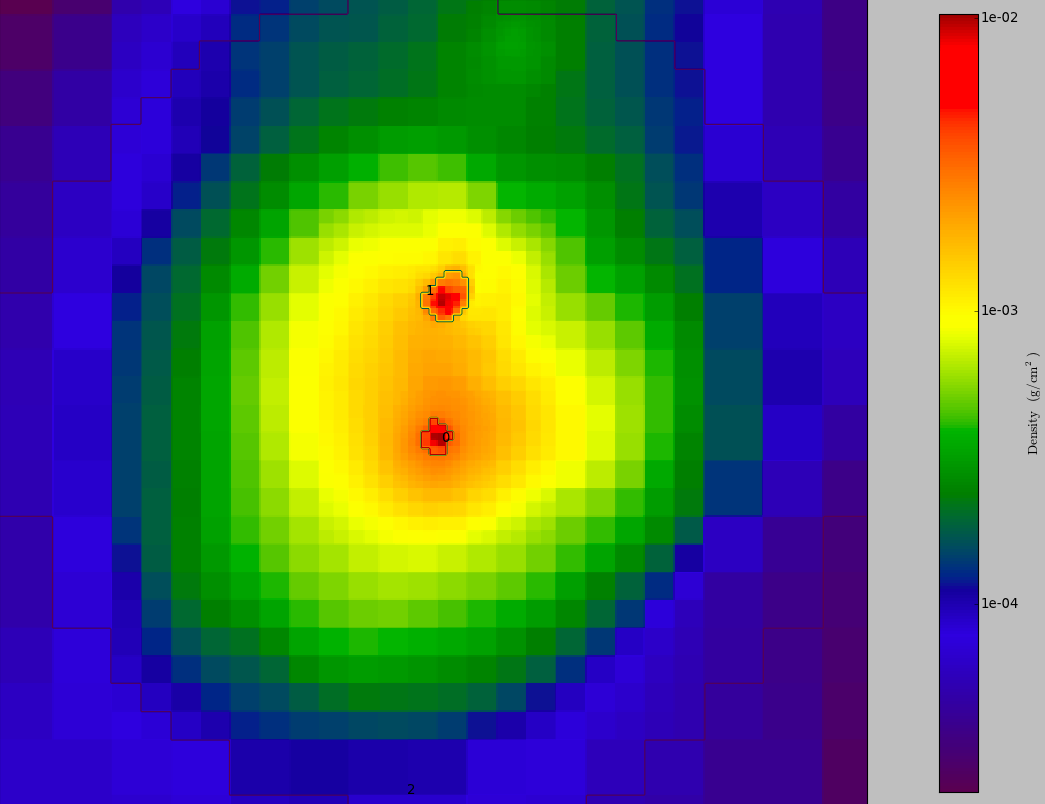
The picture above is an example of the output of the script. The colors indicate gas density, blue to red is low to high. If you look at the full-sized image, you can see that there are two dense clumps numbered 0 and 1. I can't just pick the most dense cluster because that might be a tiny blob of matter falling into the larger cluster; more care is needed. So I need to make the decision with my adaptable brain. The script spits out the image, and then I have to input which clump I think is the most central clump, and a record is made which I'll use for the next step in my chain of analysis. I spent most of today looking at these pictures and entering numbers. Yay for tax payers!
This is very similar to the Galaxy Zoo project that aimed to identify the morphology of actual galaxies, but my effort is on a much smaller and simpler scale.
So - which clump do you think is the most central above?
Volume Rendered Movies
It's show-and-tell time! Below are two movies I made using the volume rendering tools of yt. I've been using yt for a few years to analyze and visualize the cosmological simulations I make with Enzo, and only recently have I had time to begin to play with the new volume rendering stuff.
The first movie is a slow rotation around the entire volume of a simulation at a contemporary epoch, which means that this image is produced from the state of simulation at its end, 13 billion years after it started. The colors correspond to the density of matter in the volume, from dark blue to white as density increases. The simulation is a periodic cube with dimensions 20 Mpc/h on a side. In comparison, the diameter of our galaxy is somewhere around one thousand times smaller. This means that the whitest areas correspond to clusters of galaxies, and our galaxy would be just a small part of one of the white blobs. Be sure to watch the movie full screen!
Below shows the time evolution of the simulation from beginning to end. This is a thin slab of the center of the simulation (10% thickness) viewed from a corner of the cube. Notice that early on the matter is very clumpy everywhere, but rapidly forms dense knots connected by thin filaments. This is how the real universe looks! After about the half-way point of the movie you'll notice that not much happens. Again, this is how the real universe looks! Much of the large-scale evolution of the universe was finished about 7 billion years ago. This movie uses comoving coordinates, that compensate for the expansion of the universe. If I were to use proper coordinates, which are the kind we use every day to measure normal things with rulers, the movie would show the simulation starting very small and then blowing up. Again, use the full screen option for the best image.
SDSC Optiportal
My adviser Professor Mike Norman, as part of his job at the San Diego Supercomputer Center, purchased an optiportal system for the new SDSC building which is opening today. An optiportal system is a wall of monitors powered by networked computers such that the screens behave as one monitor. Very high resolution images and movies can be tiled across the screens, as you can see below. Movies and animations can also be tiled across the screens.
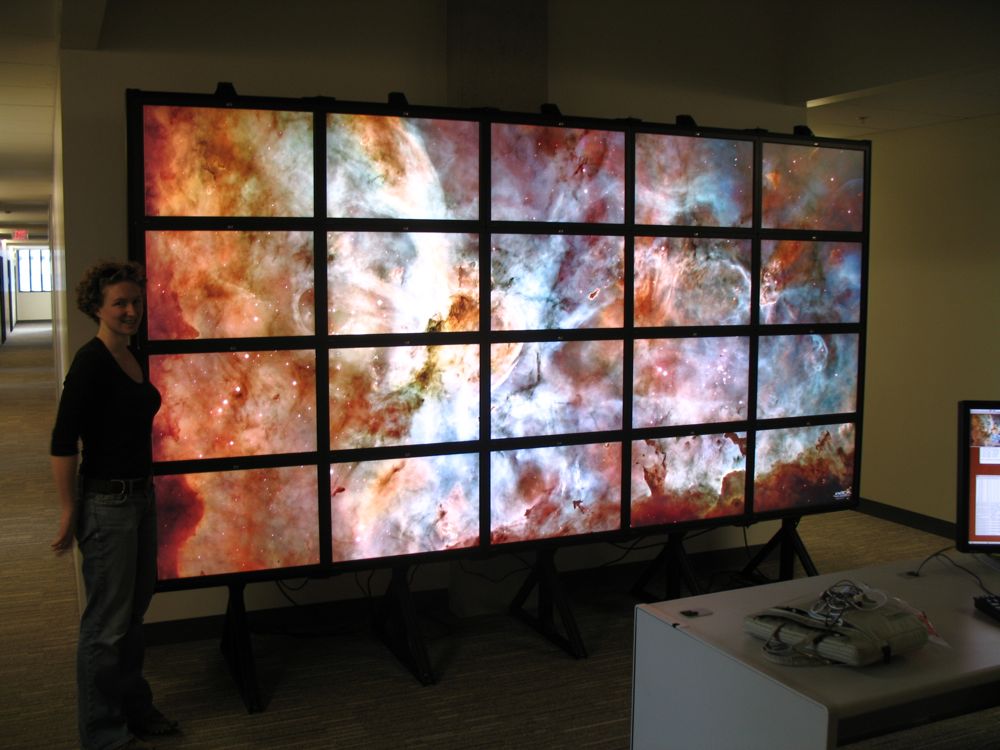
My labmates and I (Rick Wagner in particular) spent the last week feverishly building the system. The primary work was to build the monitor rack. It has many bolts and sliders and adjustments. We arranged to have two holes drilled through the wall for the monitor cables. The 30-inch screens require a very particular kind of cable and getting enough of the right kind that were long enough to reach all the screens was surprisingly difficult.
My main task was to convert some of the publicly available high-resolution astronomical images into tiled TIFFs. Tiled TIFFs break the data up into easy to scale tiles, which is essential for the optiportal. I used many of the images from this page (link broken), including the 403 megapixel Carina Nebula image linked there. It was quite frustrating. I tried half a dozen computers and iterations of ImageMagick and VIPS before I finally got a combination that worked.
In some ways, this is worse than a projector. There are gaps between the screens. This requires multiple expensive computers and many, many cables. However, there are some big advantages to this setup. There is no projector that has anywhere the same resolution as this optiportal (2560x1600x20 = 81.92 megapixels). Just one of the monitors is better than all but the most specialized and expensive projectors. The screens are bright and clear, even in normal lighting conditions. Unlike a projector, standing in front of the screen doesn't shadow the image. It has to be seen for yourself; twenty 30-inch monitors are awesome to behold.
Each four-monitor column is powered by a HP xw8600 workstation with one 4-core 2.33GHz Xeon processor, 4GB of RAM, two NVIDIA Quadro FX4600 768MB video cards with dual output, running Ubuntu 8.04 LTS. There is a sixth identical workstation that serves as a head node which sits in front of the screens and controls the output on the wall. There is also a HP ML370 server that has a 1TB RAID5 disk array, and has room for an additional 1TB. Eventually, all the machines will be connected by a 10Gb CX-4 network using a ProCurve 6400cl-6XG switch, and the head node and disk server will be connected to the outside world with a 10Gb optical connection. The monitor array is controlled using CGLX which is developed at Calit2, which is here at UCSD.
Science will not be performed on the optiportal, at least the major calculations won't. Instead, visualizations of simulations run on supercomputers will be displayed and analyzed. The human eye and brain is still a superior judge of the accuracy and meaning of data than a set of conditional equations. It is often necessary to actually see the raw data as clearly as possible. The point of the eventual 10Gb optical connection is that various parallel visualization programs like VisIt and ParaView will be practical. These programs do the data analysis on a remote supercomputer and the visualization is sent to the optiportal in real time for display. In this way, terabytes of raw data don't have to be transferred off the supercomputer, and the computationally intensive part of the visualization takes place on the supercomputer, which has far more processors, RAM and disk space than the optiportal. I hope to someday have some of my data displayed in this fashion.
Music History Graph

Above is a small part of my music listening history as reported to last.fm over the last year and a half. Time is plotted left to right, overall number of tracks by the width of the shape, and the colors represent individual artists. I used LastGraph3, which if given your user name will make a set of graphs from your data.
If you click on the image above, you'll see the full history. It looks like I go through periods where I listen to a fair bit of music, and then stop, and start again. I think there's a fair amount of smoothing of the data. I think my history would look even more jagged without smoothing.
I like plots like this because they show multidimensional data using colors and shapes in an intelligent way. Of course the classic example is Minard's famous depiction of Napoleon's 1812 Russian campaign. I think everyone should have to learn how to make good plots, and understand how to read one. When I was a TA, I constantly had to remind students the point of making graphs - I think nearly all of them felt it was busy work rather than a way to organize and visualize data; a way to recognize a physical effect.

Just like significant figure errors (I am bothered enough by those to contact newspaper reporters: I've done it in the past), I cringe at the sight of misleading or poorly organized graphs. The worst offenders tend to use Excel, whose plots are instantly recognizable as probably being garbage. I also dislike the USA Today charts and many plots seen on the various network evening news shows. Too much artistic influence from graphics artists (no offense K.P.!), and not enough substance.
Ride History Mashup
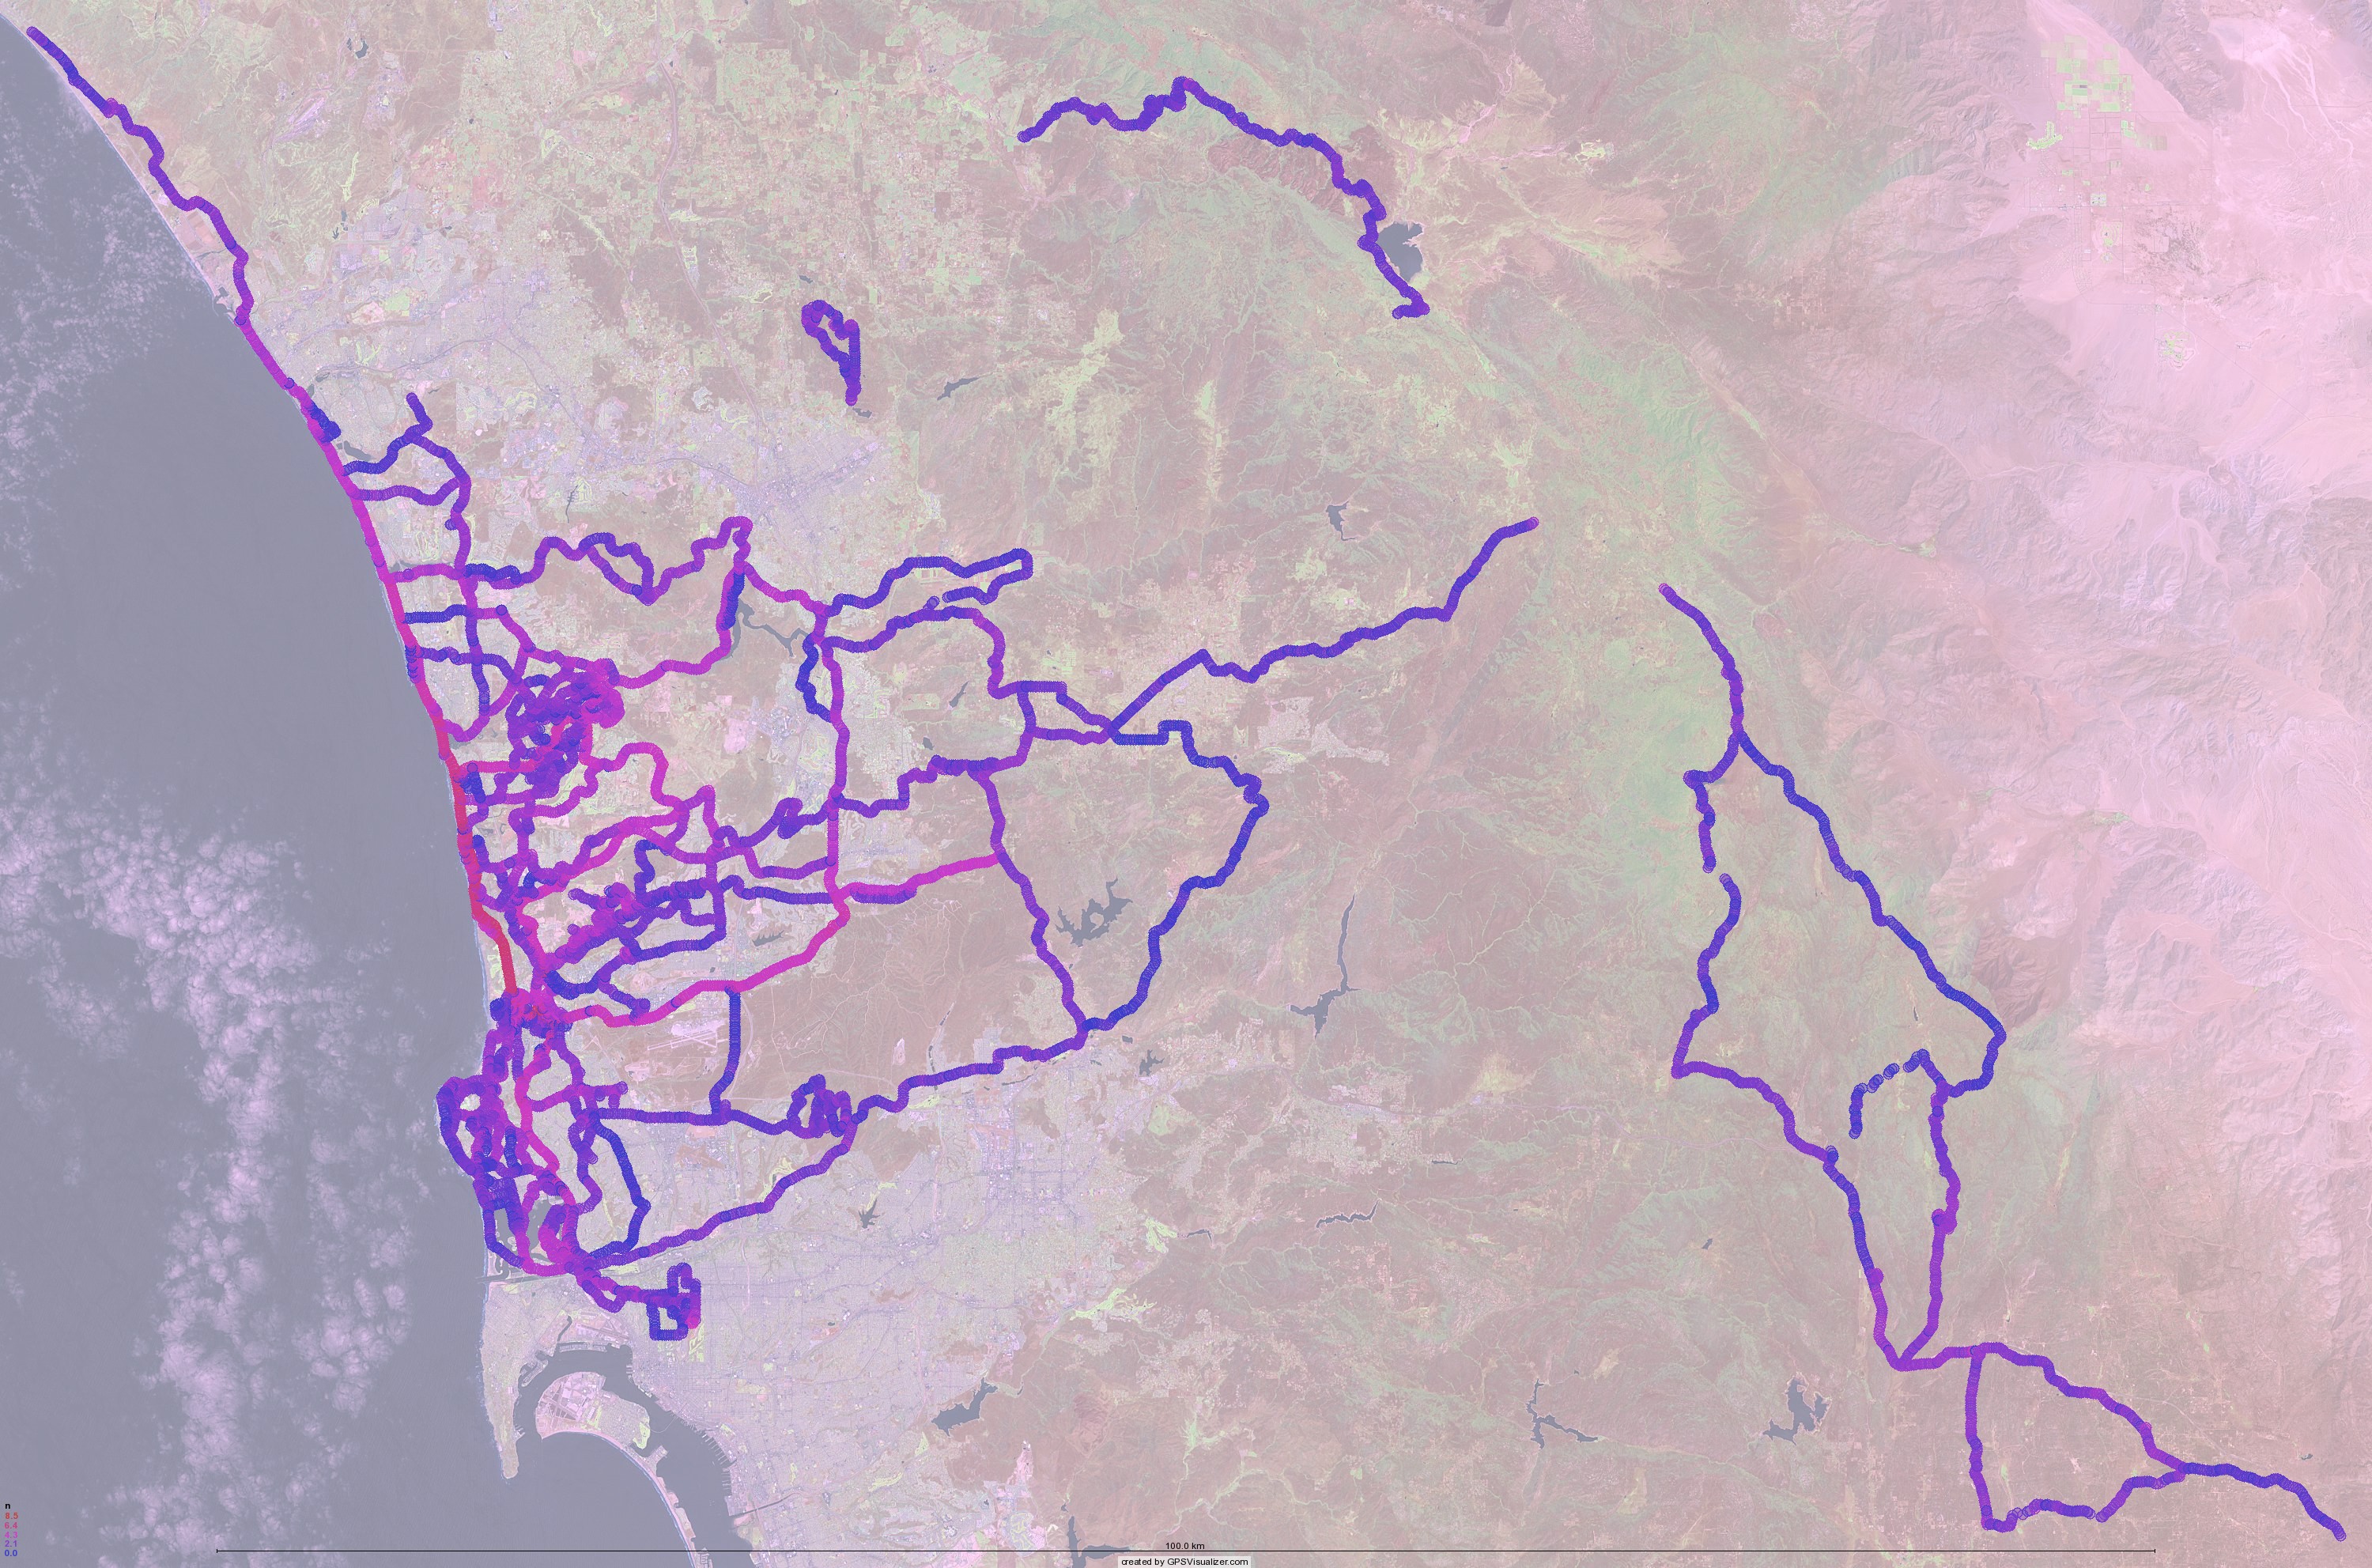
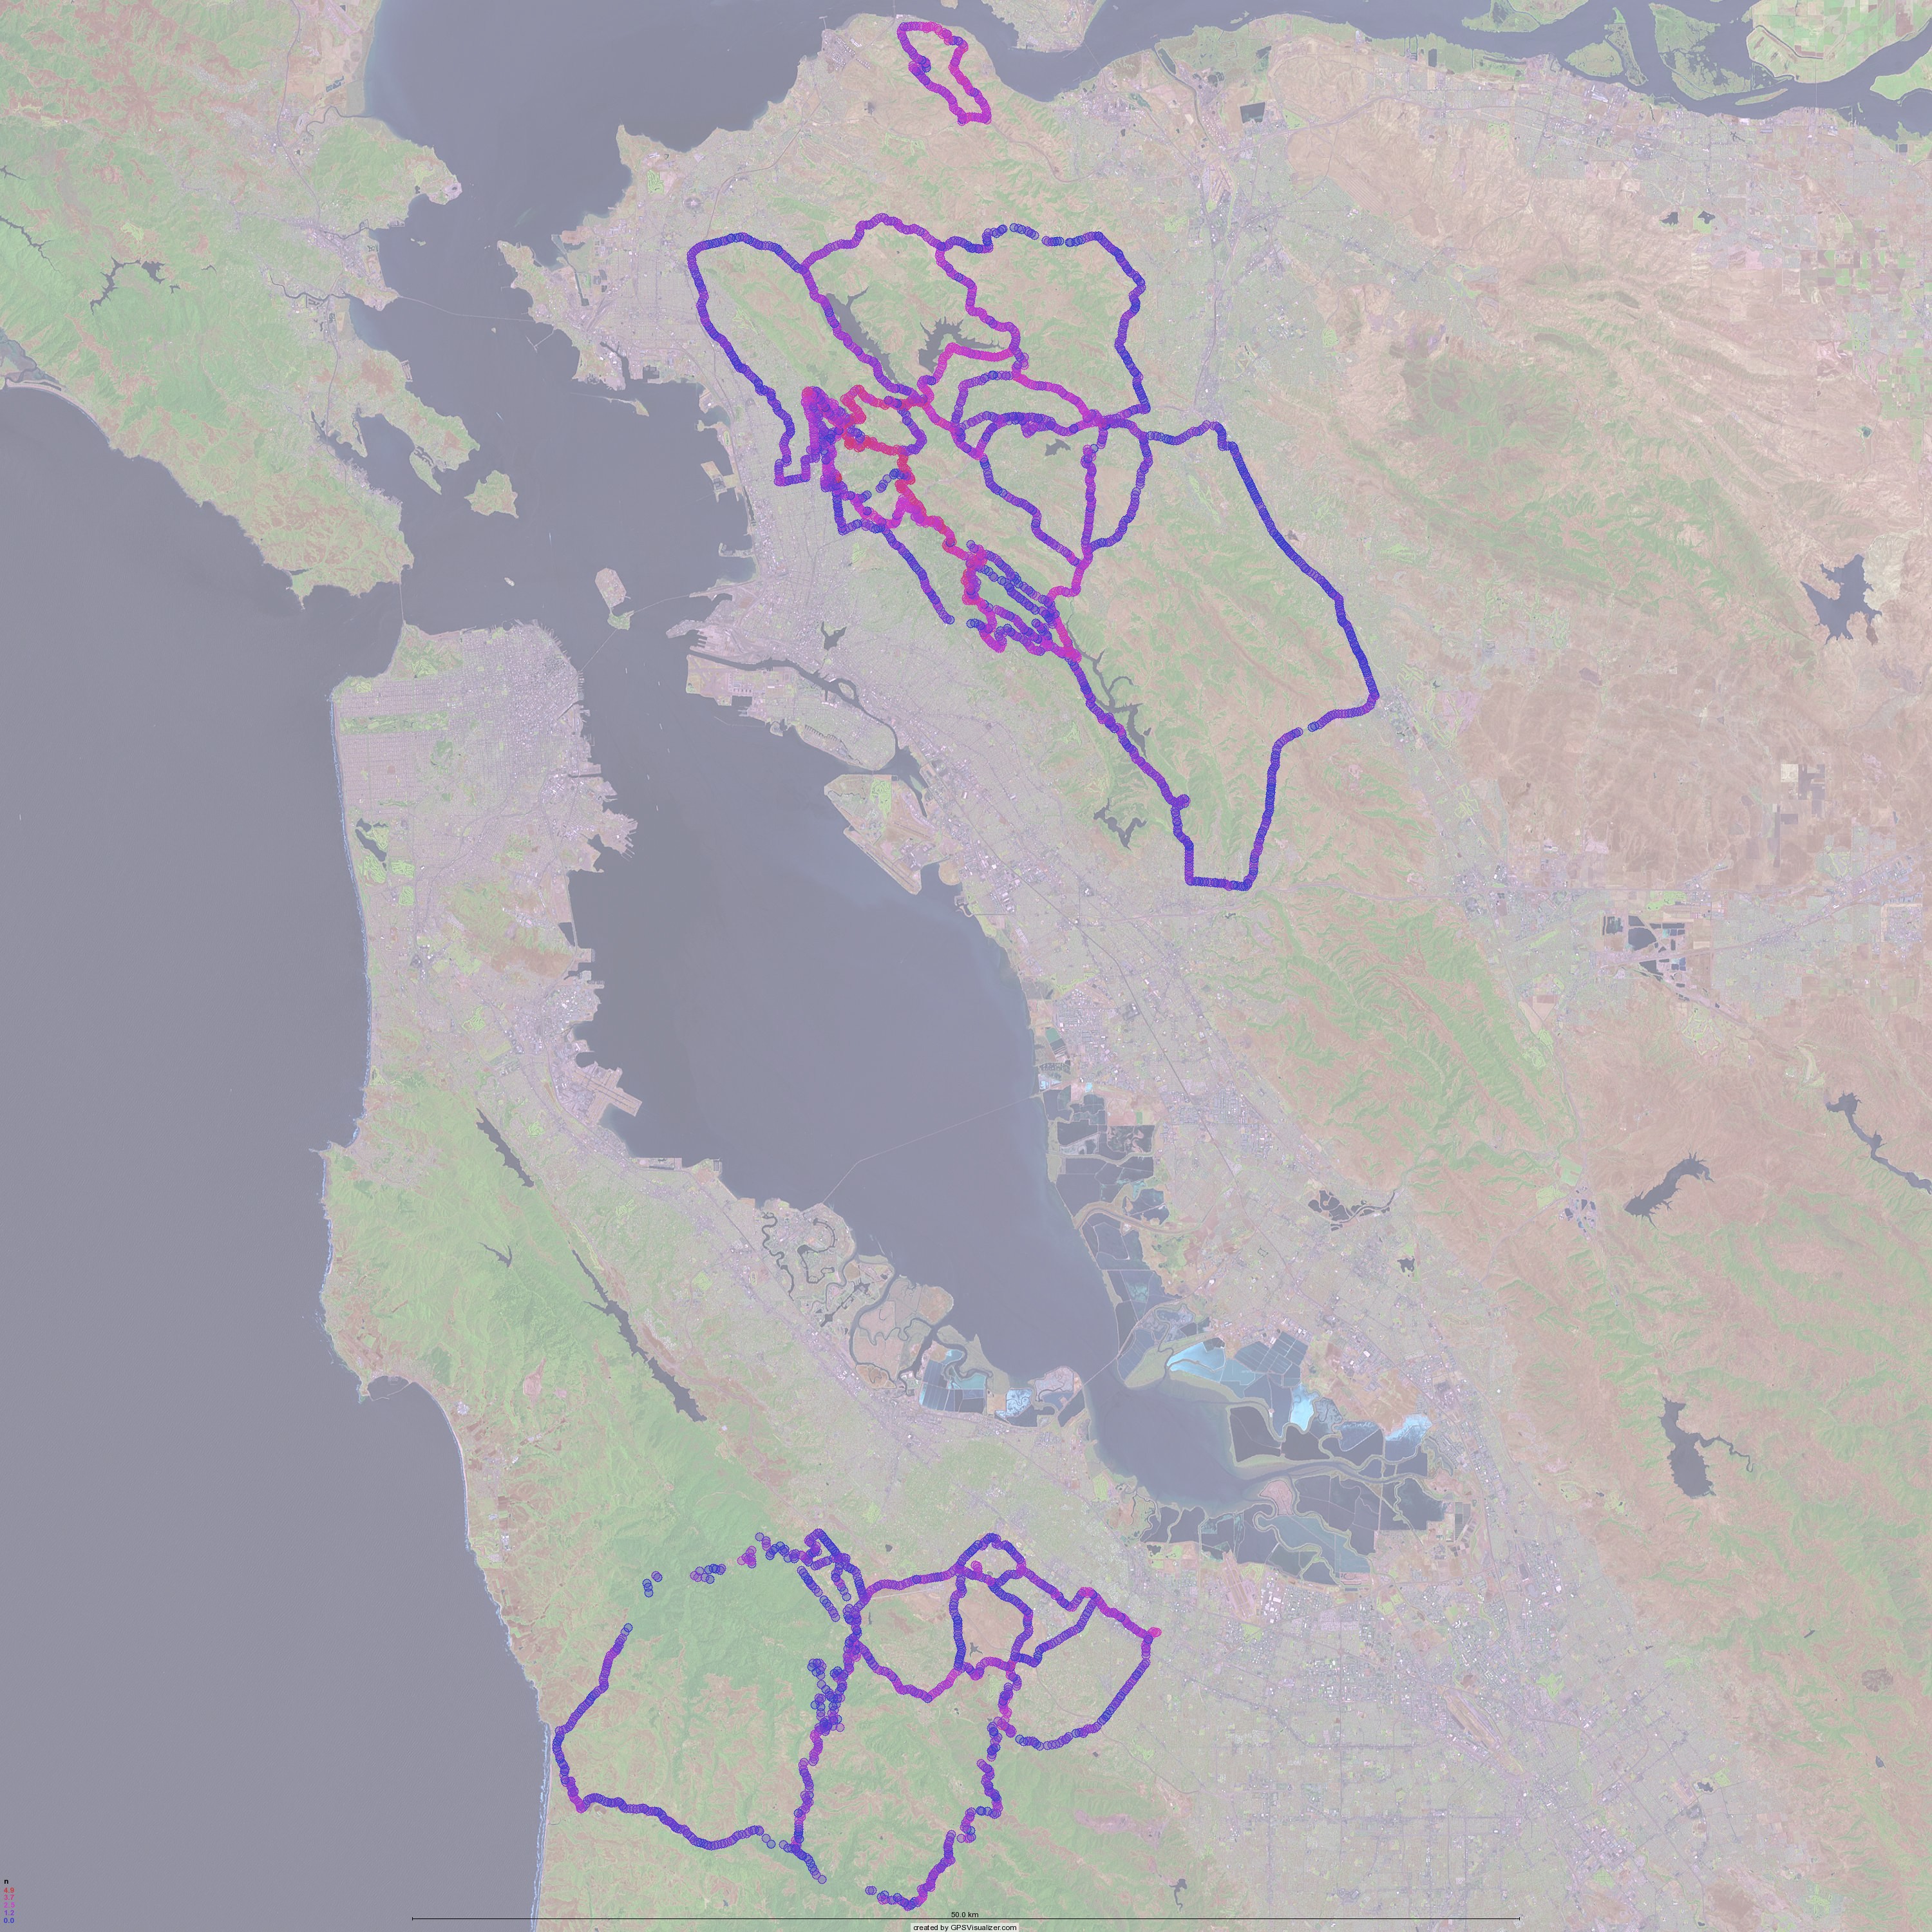
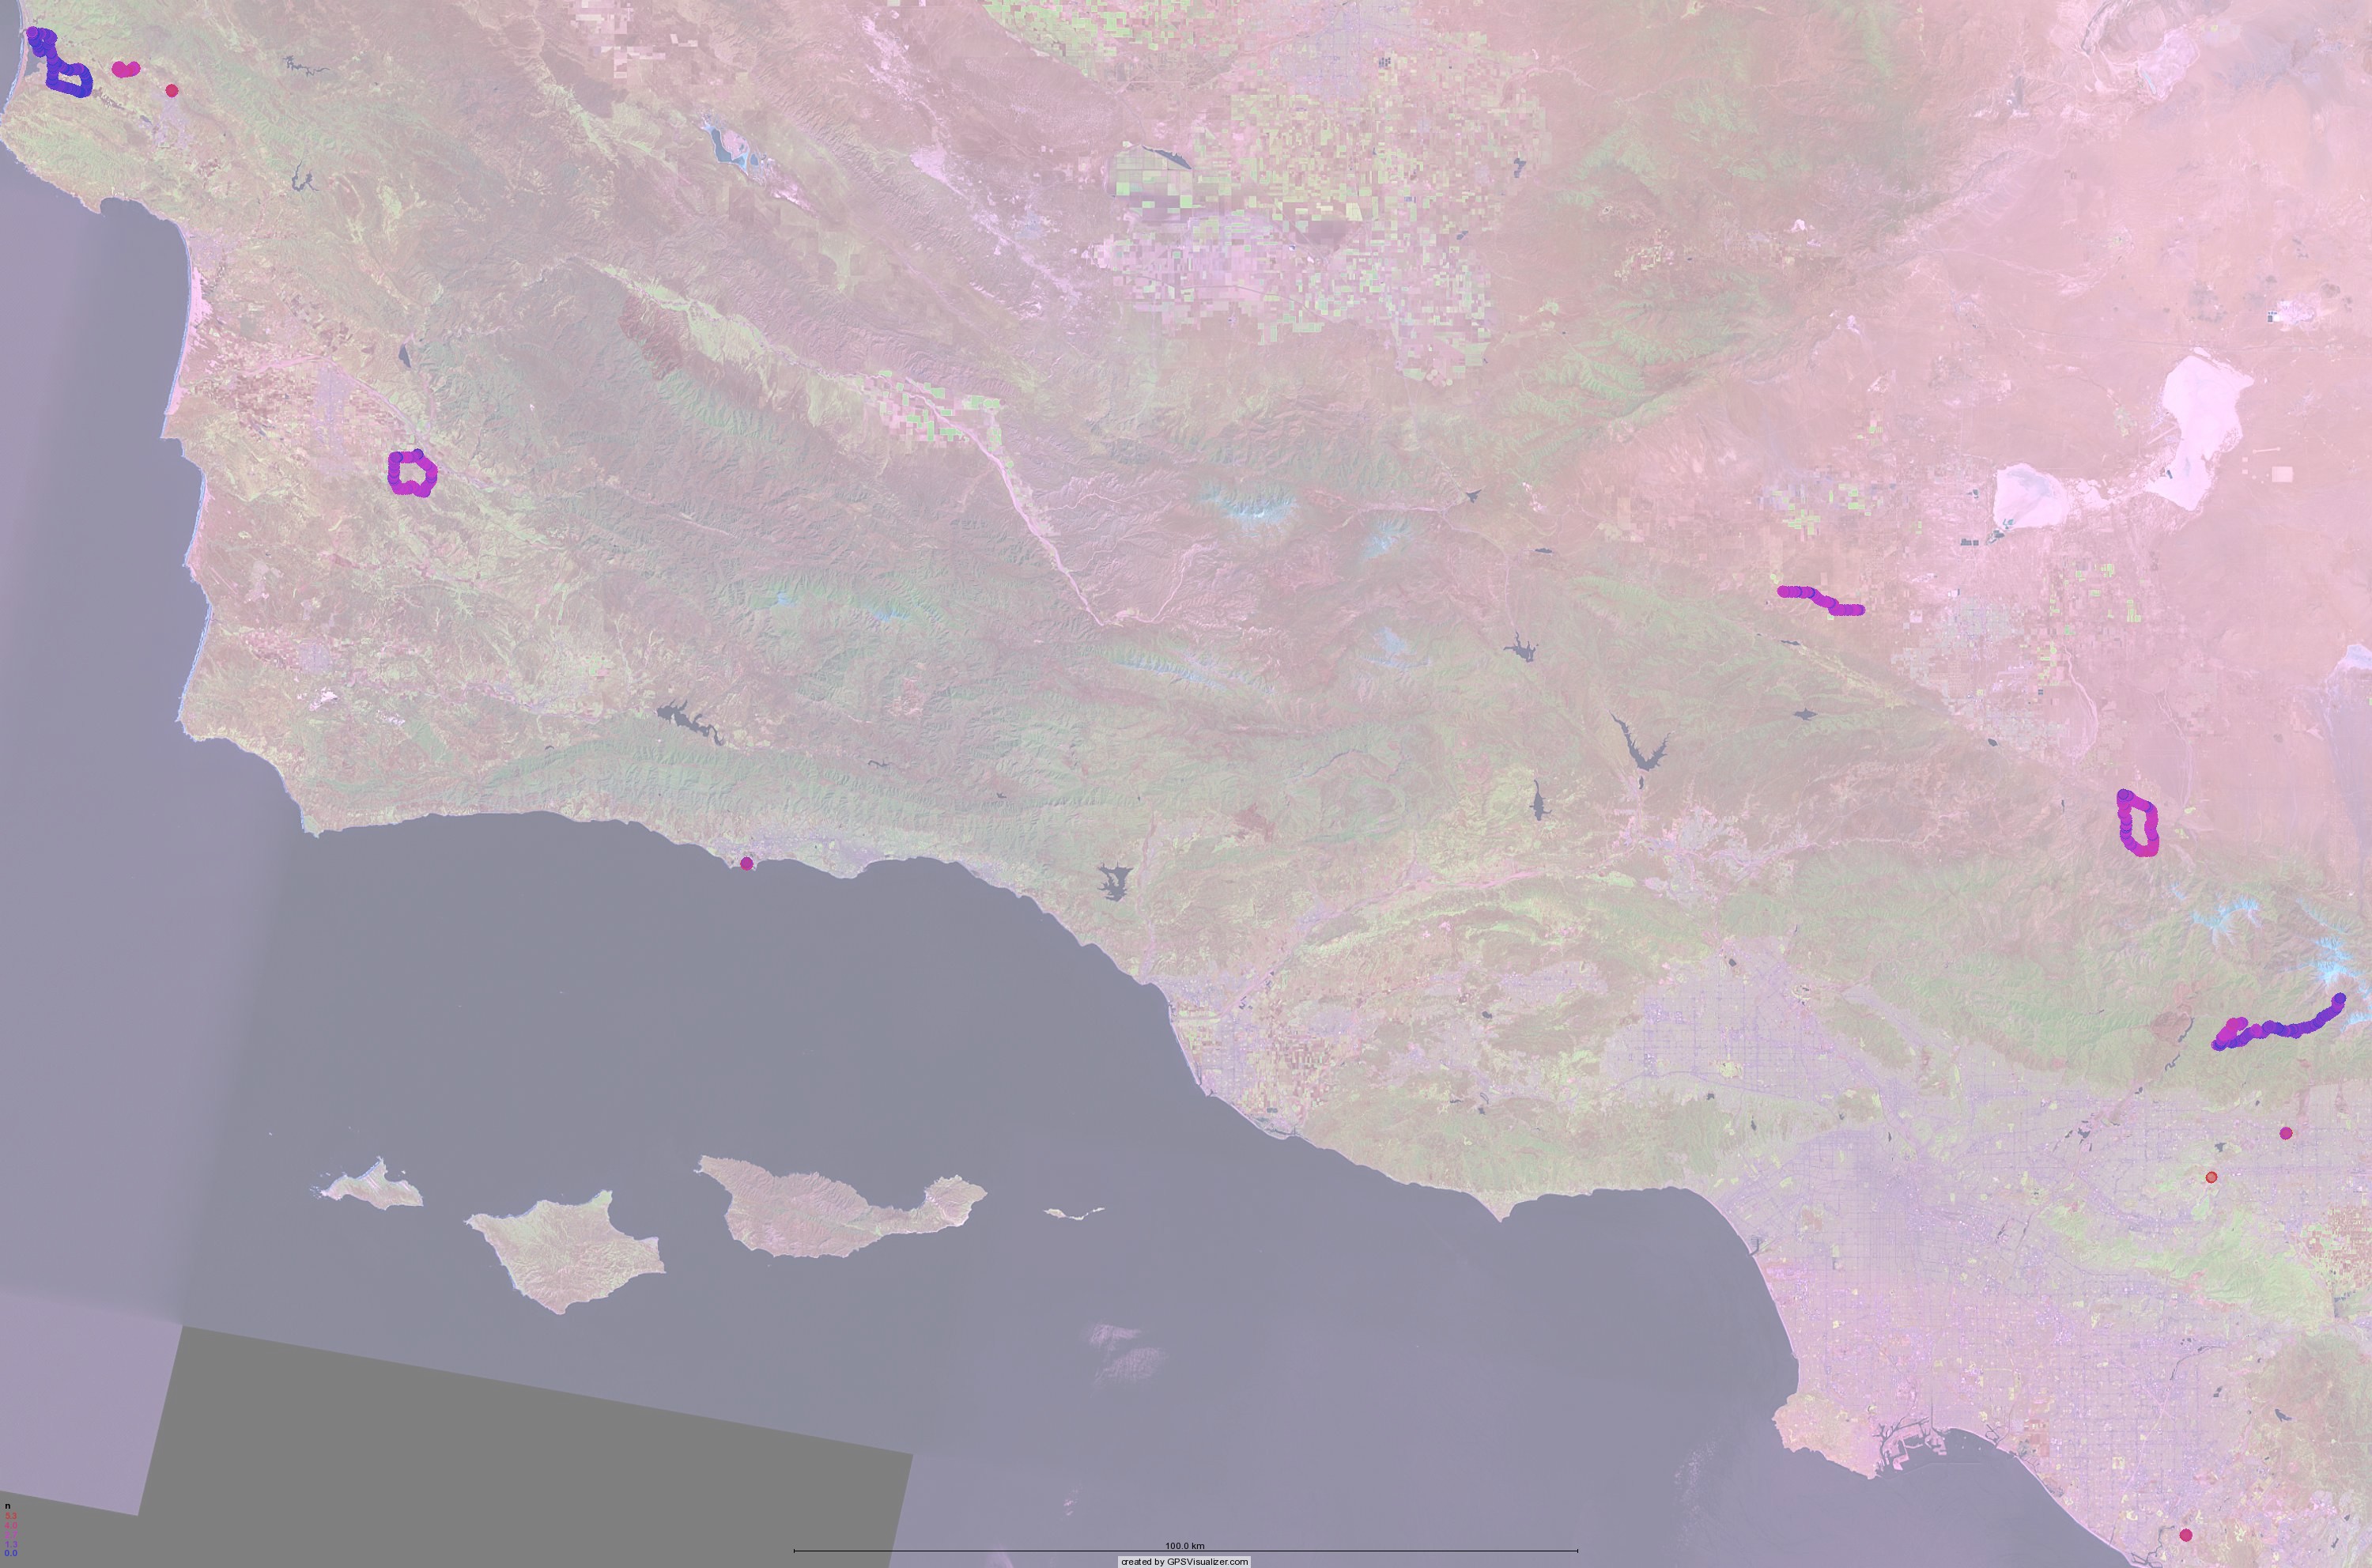
Below are some mashups showing the frequency density of where I have ridden my bikes in the last three years. (I never use my GPS on the track, so velodrome riding is not represented here. And besides, that isn't very interesting.) The circles on the maps represent a place I have passed through, and the color how many times. Red means many, perhaps as many as 5000 times for the area near my apartment, and blue means few, as few as once. That 5000 doesn't mean I've done 5000 rides, it means that there are 5000 GPS waypoints in the 100 meter radius circle around that particular point. As waypoints are recorded closer than 100m apart, the same ride could have multiple waypoints inside each circle. Also note that the circles on the map are much larger than 100m.
Click on each for a larger view.
I made a Google Earth KMZ file containing all the points. If you open it, be patient as it will take a bit of time to load. Download it here.
I think I'm planning on posting the code here, as I think other people might like this fun bit of code. But I want to clean it up a bit before I make it public.